
Practical guide
Missing robots.txt: is it a problem for Google?
A missing robots.txt does not, by itself, prevent Google from crawling or indexing your public pages. A 404 normally means there are no crawl restrictions in that file. Investigate the response and your intended rules before adding or changing anything.
Qlinnt · Reviewed
Crawling and indexing are different decisions
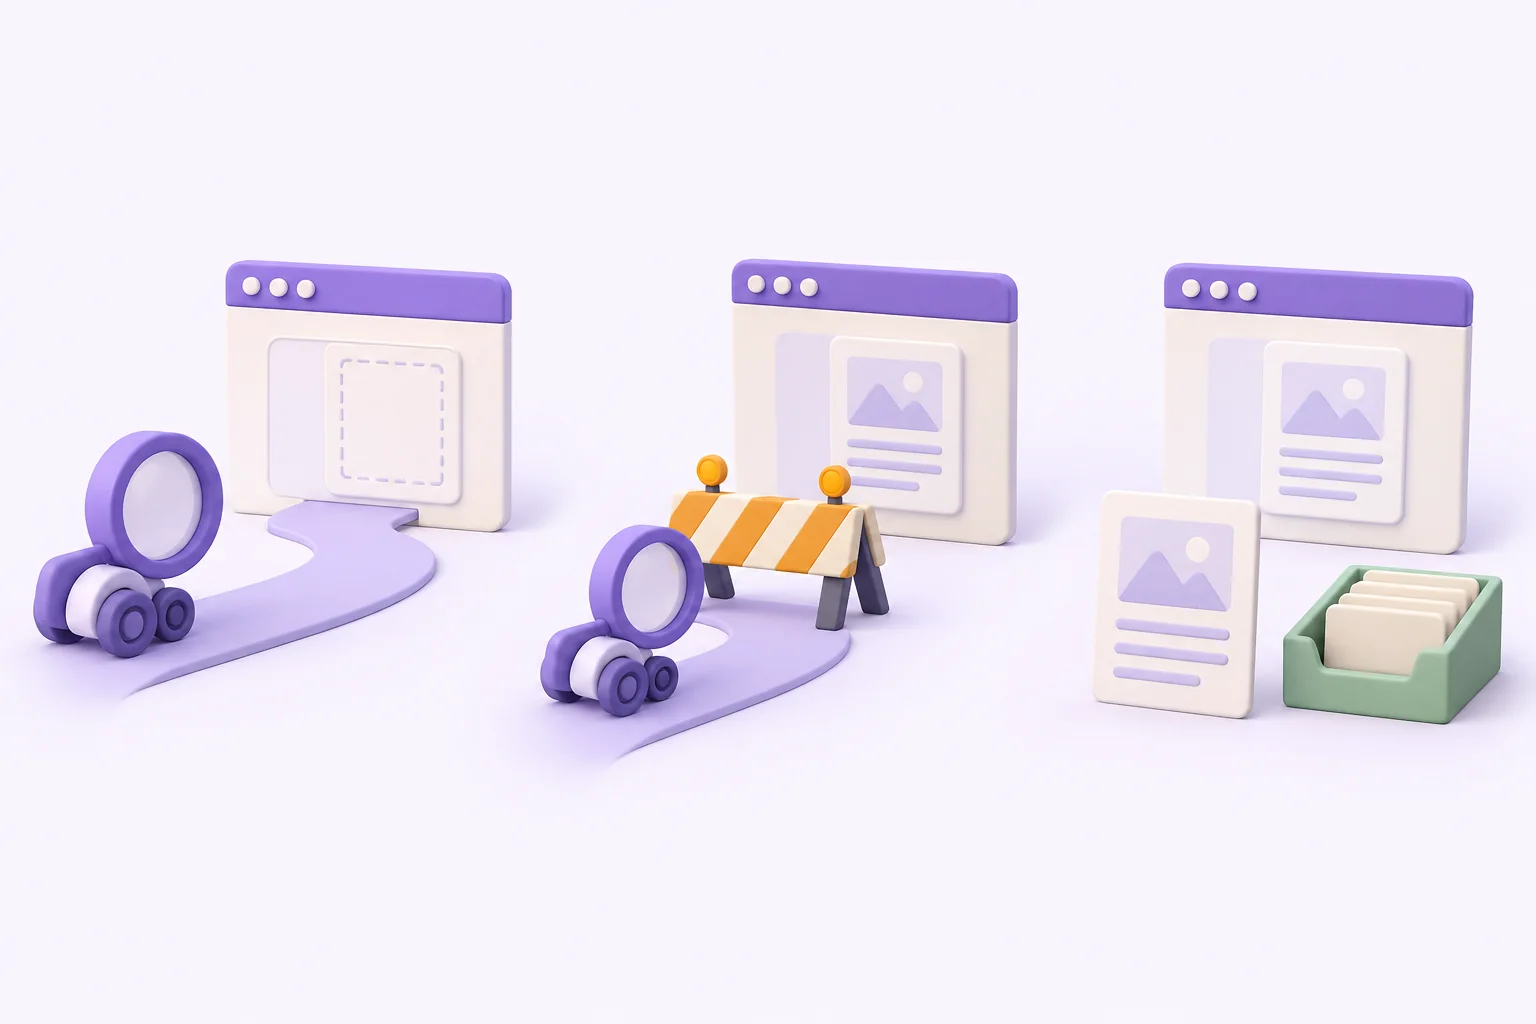
- Missing robots.txt
GET /robots.txt → 404Usually means no crawl restrictions in that file. It does not, by itself, prevent indexing.
- Crawling blocked
User-agent: *
Disallow: /
Asks compliant crawlers not to fetch the site. This is a crawl rule, not an instruction to remove URLs from the index.
- Indexing excluded
noindexAfter an eligible crawler fetches and processes the directive, the page should be excluded from its index. Do not put noindex in robots.txt.
Blocking crawling does not reliably remove an indexed URL. A crawler must be able to fetch the page to read its noindex directive.
Check the response before changing your site
Request /robots.txt on the exact production origin, including HTTPS and the correct hostname. A file on www.example.com does not define the rules for a different host. A 200 response should contain plain-text rules, not a login screen or the application’s HTML fallback.
Use a site you own or are authorized to inspect. This request reads the public response; it does not reproduce a verified Googlebot visit.
curl -i https://example.com/robots.txtDecide whether there is a problem
Missing configuration, intentional restrictions and server failures need different actions. Do not remove safeguards simply to make a checker turn green.
| What you observe | What to check | Next step |
|---|---|---|
| 404 or 410 | No robots.txt file exists at this origin. | No file is required for unrestricted crawling. Add one if you need crawl rules or a sitemap reference. |
| 200 with plain-text rules | Read the matching user-agent group and Allow/Disallow paths. | Keep deliberate rules. Investigate an unintended block of a public page. |
| 200 with HTML | The server may be returning the application shell instead of a real file. | Publish a text response at /robots.txt and check it after deployment. |
| 429 or 5xx | Rate limiting or server availability may prevent retrieval. | Investigate logs and availability. Do not treat this as an ordinary missing file. |
For a static site, publish a real text file
If you need a file, place robots.txt in the deployment’s public root. Replace the example sitemap origin. This unrestricted example is appropriate only when you intend to allow crawling of the site.
Disallow is not authentication. Protect sensitive pages with access controls. To keep a reachable page out of search, use a noindex directive and let the crawler read it.
User-agent: *
Allow: /

Sitemap: https://example.com/sitemap.xml
For Next.js App Router, generate the file
Create app/robots.ts, or src/app/robots.ts if your project uses src. Use your production domain, not localhost or a preview URL. Publish this route once; avoid a second static robots.txt that conflicts with it.
import type { MetadataRoute } from 'next';

export default function robots(): MetadataRoute.Robots {
  return {
    rules: { userAgent: '*', allow: '/' },
    sitemap: 'https://example.com/sitemap.xml',
  };
}
Verify the deployed result
Repeat the same request after deployment and check the status, body and exact hostname. Then inspect an important public URL in Search Console. A readable robots file does not establish that the page is indexed or ranks.
- The live response is the text you intended, not a preview or HTML fallback.
- Public pages do not carry an accidental noindex directive.
- The sitemap lists intended canonical public URLs.
- Authentication and intentionally excluded report pages remain protected.
What Qlinnt can and cannot confirm
Qlinnt checks public robots and sitemap responses and other technical signals. Its automated robots check is not a complete per-user-agent rules simulator. Use Google’s reports and your server evidence for crawler-specific questions.
If an AI builder reports success after changing a file, verify the deployed URL rather than relying only on the chat response. Run a new scan to inspect the public signals again.
Sources
Scan your public website
Start with a free scan. Verify your email to read every finding explained. Full evidence and tool-adapted prompts require full access; new purchases are currently paused.
Scan for free